Most companies using Oracle Fusion cloud have a pressing need to push the Fusion data to their Fabric Lakehouse to maintain a single source of truth. These companies typically come across any of the following combinations of Data Migration/ETL needs for each table they want to pull from Oracle Fusion:
- Type of data pull from source table - Full data pull or Incremental data pull
- Data insertion in target table - Insert new rows or update existing rows or both
- Frequency of automated refresh – Hour-based scheduling (runs every X hours based on FREQUENCY_IN_HOURS).
- Pipeline monitoring – Tracks execution status, start time, end time, and error description for each table run.
In some cases, they might have a composite primary key (a set of concatenated values from different columns of the table to uniquely identify each row). Some tables may not have time-based columns to facilitate incremental loads, for which the primary key is used as a reference to perform the incremental load.
This article will help you to handle all of the above scenarios with a single Fabric pipeline (that refers to a Lookup table).
The lookup table acts as a configuration controller for Fabric pipelines. Each row in the table represents a data load job, including source/destination table details, load type, execution frequency, and watermark column information for incremental loads.
Prerequisites:
1. Required Setup:
- Windows Server with On-premises Data Gateway and BI Connector
- Install and configure On-premises Data Gateway from Microsoft
Note: It's possible to use an existing gateway as well - Install BI Connector Server edition and activate it using a license key.
- Install and configure On-premises Data Gateway from Microsoft
- Admin Access to Gateway Server
- Admin access is required to set up System DSNs in ODBC.
- Microsoft Fabric Workspace and Lakehouse
- A Microsoft Fabric Workspace must be available.
- A Lakehouse must already exist in the workspace and Lakehouse schema support must be enabled.
2. Recommended Configurations:
- Windows Server 2016 or above (can also be set up on a VM on the cloud)
- .NET Framework 4.7.2 or above installed
- Minimum of 8 CPU cores, 8 GB RAM, and 80 GB hard disk space
- Strongly recommended to disable hibernate/sleep on this server.
Step 1: Download the Pipeline Template
Please Contact us or email support@biconnector.com to get our ready-to-deploy Fabric Pipeline template.
Step 2: Import the Fabric Pipeline using the template:
2a. Extract the ZIP Folder
After Downloading the provided ZIP folder.
Right-click the file and select Extract All.
After extraction, you will find the following two files:
Pipeline Template named FUSION_TO_FABRIC_LAKEHOUSE_USING_BIC (ZIP Folder)
→ Contains the Fabric pipeline template to be imported.- Python Notebooks
→ Contains the Python notebooks required for the Fusion-to-Fabric Lakehouse pipeline setup and execution.
2b. Creating BI Connector ODBC Connection:
Note: Before proceeding, ensure that the BI Connector DSN is correctly configured and that the required BIC tables have been created by adding all relevant Oracle Fusion folder paths where the OTBI Analysis Reports are located. These are required for the ODBC Linked Service to successfully establish a connection and extract data.
For guidance on how to create a DSN and BIC tables, refer this article .
- Go to "Manage connections and gateways".
- Click "+ New" .
- Select "On-premise"
- Select your Gateway cluster (same as above).
- Enter a descriptive name for connection: Your_Connection_Name(e.g. Fusion_Reports).
- Select Connection type “ODBC”.
- Fill in details:
- Connection string: dsn=YOUR_DSN_NAME (replace YOUR_DSN_NAME with your actual BI Connector DSN)
- Authentication: Basic
- Username: Your Oracle Fusion username
- Password: Your Oracle Fusion password
- Click “Create”.
2c. Import and Configure Python Notebooks
- From the extracted ZIP folder, locate the Python Notebooks ZIP folder.
- Extract the Python Notebooks ZIP folder.
- In the same Microsoft Fabric Workspace where you are going to create pipeline, import the required Python notebooks.
- Open each imported notebook and map/attach it to the Lakehouse that you created for the Fusion-to-Fabric Lakehouse pipeline.
- Ensure that the notebooks are connected to the same Lakehouse that will be used as the destination for the pipeline.
2d. Create and Configure the Fabric Pipeline
- In the same Microsoft Fabric Workspace, create a new Data Pipeline.
- Import the provided FUSION_TO_FABRIC_LAKEHOUSE_USING_BIC pipeline template.
- Map the connection :
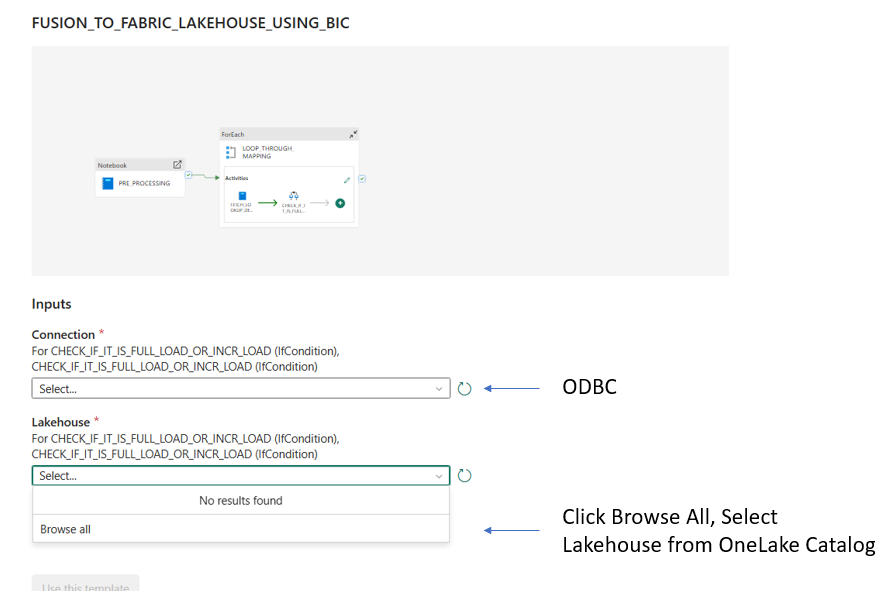
2e. Configure Pipeline Parameters
Add and configure the following parameters in the pipeline:
lookup_table_schema_name→ Enter the schema name where the lookup table is created.lookup_table_name→ Enter the name of the lookup table.notebook_workspace_id→ Copy the Workspace ID from the Microsoft Fabric Workspace URL.- Notebook ID parameters (3) → Copy the Notebook ID from the URL of each respective notebook and enter it in the corresponding notebook ID parameter.
After entering all the required values, click Save to save the pipeline parameters.
Step 3: Create the Lookup Table in the BI Connector
3a. Create New Lookup Table
In BI Connector , Navigate to the Data Pipelines section.
Click + New Lookup Table.
Enter the desired Lookup Table Name.
Note: Use a lowercase name for the lookup table. For example:fusion_lookup.Select the Fusion Data Model Data Source created in BI Connector.
Enter the Destination Schema Name.
Note: Use a lowercase name for the schema. For example:dbo,fusion_dev.Select the Destination Warehouse as Lakehouse
Click Next.
Note: Since Microsoft Fabric Lakehouse is case-sensitive for table and schema names, best practice is to use lowercase names for the lookup table and destination schema to ensure consistency and avoid potential case-sensitivity issues.
3b. Select Base Tables and BIC Tables
- In the Base Tables and BIC Tables section:
You can manually select required tables from searchable drop down
OR- Bulk paste table names if needed.
For Base Tables:
BI Connector will automatically:
Fetch the Primary Key
Retrieve all Column Names
Automatically select LAST_UPDATE_DATE as the watermark column (if available)
Assign the correct Watermark Format
For BIC Tables (Custom SQL Queries or Existing Data Models or pre-built Queries):
You must manually provide:
- Primary Key – Add if available; mandatory for incremental load. Without it, only full load is supported
- Watermark Column – Required for incremental load
- Watermark Format – Only needed if the Watermark Column is a timestamp; otherwise, leave blank
Click Save after configuration.
3c. Download and Execute Table Scripts
In the Actions column, select the required option:
Download CREATE TABLE statement
Download INSERT statement
Download as CSV
Download as Excel
Use the downloaded CREATE TABLE and INSERT queries to create and populate the lookup table in the Fabric Lakehouse.
3d. Set the Lookup Table Name in Fabric Pipeline
- Add the Lookup Table Schema name in Fabric Pipeline under Parameters lookup_table_schema_name , where lookup tables was created
- Add the Lookup Table name in Fabric Pipeline under Parameters lookup_table_name
- Publish the changes.
To learn more about lookup table, please refer this article.
Step 4: Configure Pipeline Schedule:
- Navigate to pipeline.
- Click on "Schedule" in the top ribbon/menu
- Turn on "Scheduled run" (toggle to "On")
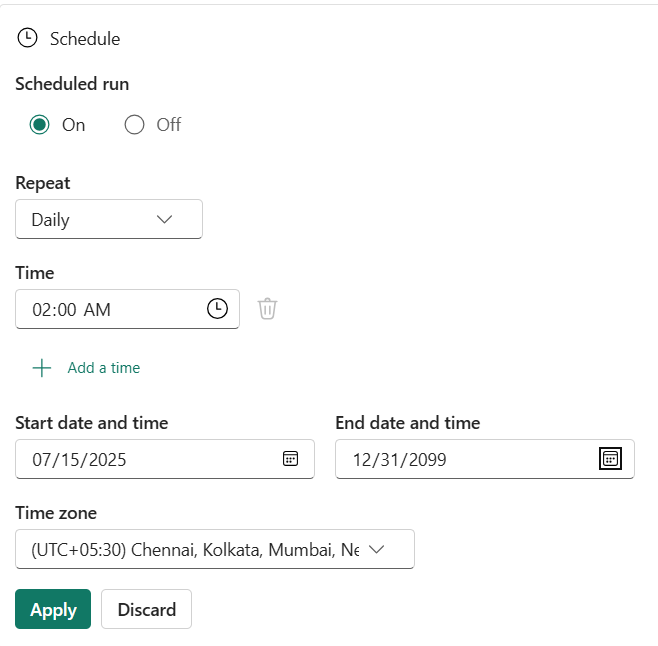
- Configure Repeat interval: Select from dropdown options like Daily, Weekly or Monthly
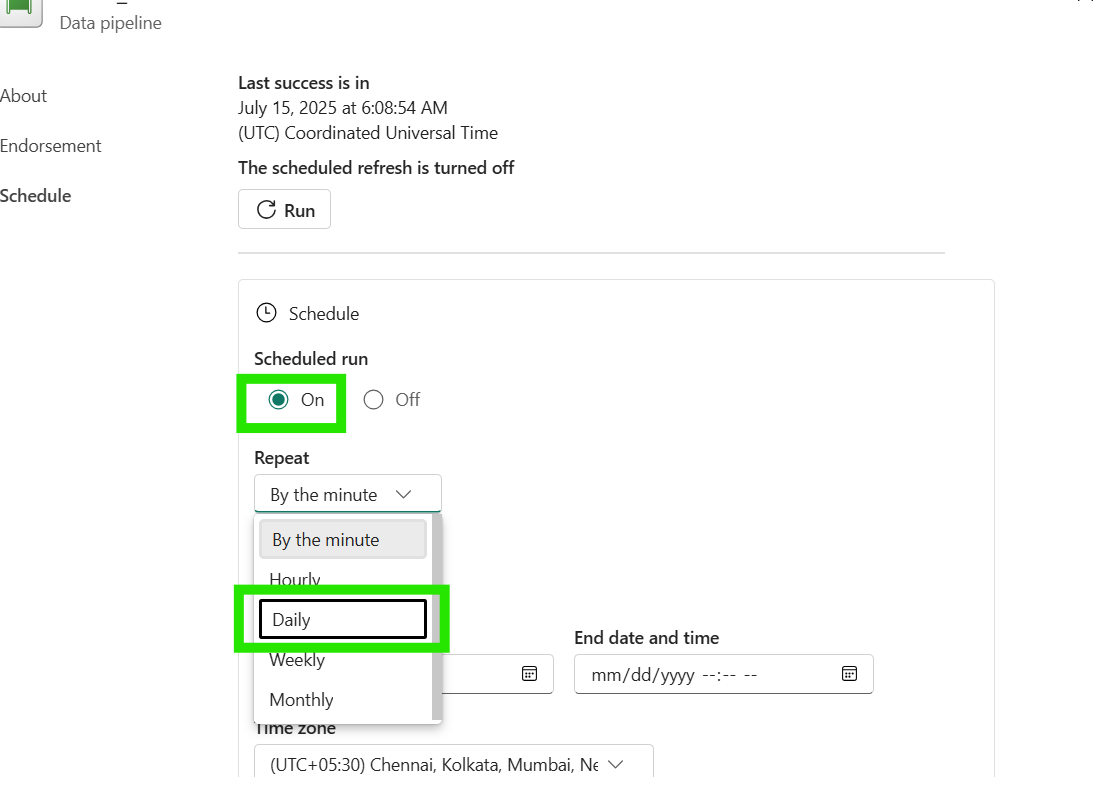
- Set Execution Time: Choose optimal time (e.g., 2:00 AM)
- Set Start date: When scheduling should begin
- Set End date: Far future date (12/31/2099) for continuous running
Note: This field is mandatory and cannot be left empty, so we use a distant future date to ensure the pipeline runs indefinitely without manual intervention - Select Time zone: Your regional time-zone (UTC+05:30 for India)
- Then click "Apply" to save the changes.
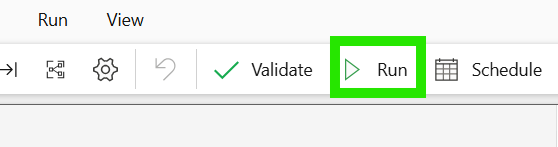
 Note: You can also run the pipeline on-demand anytime by clicking the "Run" button in the top ribbon, regardless of the schedule.
To see more on frequently asked question, please refer this article.